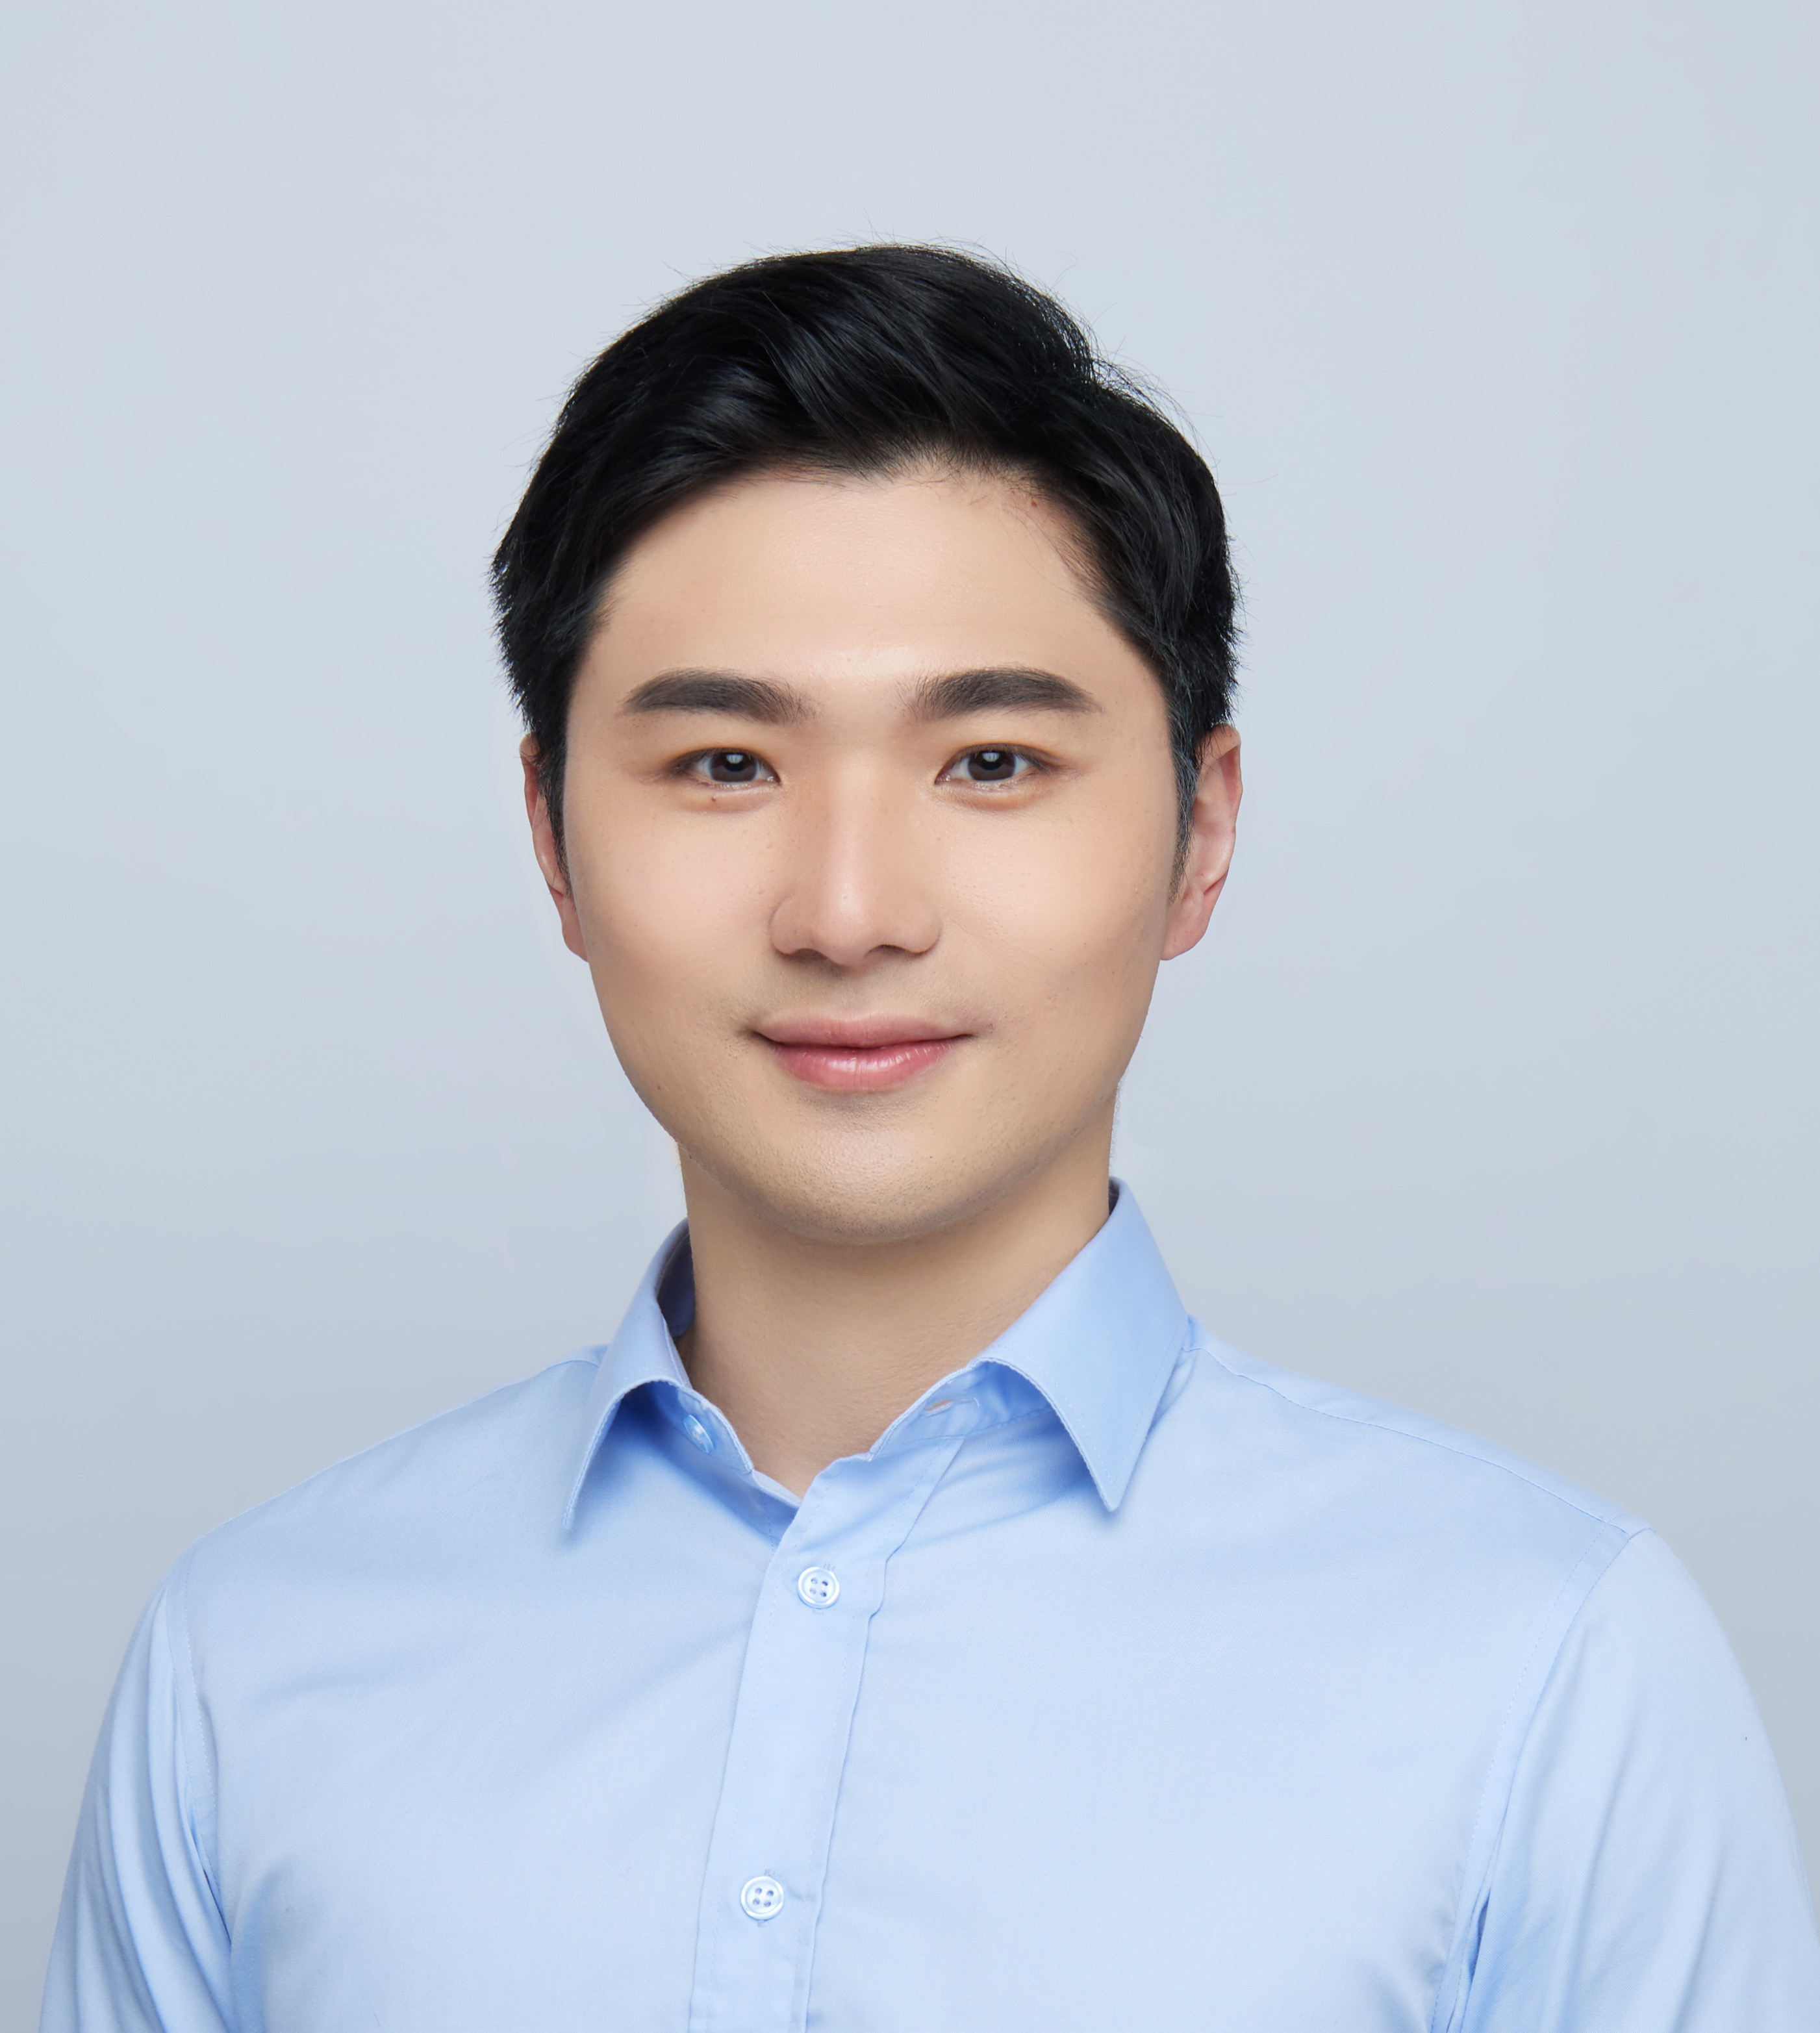
Biography
Hi! I’m Chia-Hsuan (Michael) Lee, a Senior Applied Researcher at Capital One AI Foundations, where I work on post-training for reasoning and agentic language models.
My current work focuses on large-scale RL post-training, including multi-teacher on-policy distillation, preference optimization, reward design, and reasoning supervision. I am currently leading the multi-teacher distillation stage for our next-generation reasoning and agentic LM, merging RL-specialized teachers into a single model for reasoning, multi-turn interaction, software engineering, terminal use, and long-horizon agentic tasks.
Previously, I built the preference-optimization stack for Capital One’s first reasoning LM, scaling DPO to 1M+ preference pairs across reasoning and instruction-following tasks. Alongside large-scale model training, I develop new post-training algorithms for more efficient distillation, finer-grained credit assignment, and better reasoning supervision.
Research
My research focuses on post-training language models to reason and act. I am particularly interested in how to scale reinforcement learning and distillation from individual capabilities to models that can reliably solve complex, long-horizon tasks.
My recent work spans three closely related directions:
Reasoning & agentic post-training. I work on large-scale training recipes that combine specialized RL experts into general-purpose models. This includes multi-teacher on-policy distillation for transferring capabilities across reasoning, coding, multi-turn interaction, tool use, and long-horizon agentic tasks.
Reinforcement learning & distillation. I develop methods for improving the efficiency and stability of reasoning post-training. Recent work includes SEAD(NeuRIPS 2026), a competence-aware on-policy distillation method based on student-teacher uncertainty, and DASH, which uses fine-grained rewards and segment-level credit assignment to improve reasoning while reducing overthinking.
Preference learning & reasoning supervision. I study how supervision quality affects reasoning-model post-training, from large-scale DPO to critique-guided training. CGD(ICML 2026) uses teacher-generated critiques and refined responses for reasoning supervision, while Decomposing the Delta studies what information in preference pairs actually drives learning.
Earlier work explored complementary directions in language modeling: long-context pretraining (DOCmT5, NAACL 2022), in-context learning (IC-DST, EMNLP 2022) and prompt-tuning (SDP-DST, EMNLP 2021), inference-time routing across models (OrchestraLLM, NAACL 2024), and LLM-free self-correction for small models (CorrectionLM).
I received my PhD from the University of Washington, advised by Prof. Mari Ostendorf in the Natural Language Processing Group, and also worked closely with Prof. Noah A. Smith. I was a research intern at Google Brain (2022), co-hosted by Ankur Bapna and Yu Zhang; interned at Google Research (2021), hosted by Melvin Johnson; interned at Microsoft Research NLP group (2020), co-hosted by Matthew Richardson and Alex Polozov.
Here is my CV
You can find me at: chiahsuan.li [at] gmail [dot] com